Google DeepMind has unveiled 'Gemini 3.8 Live' and 'Gemini 3.8 Live Extended Thinking,' voice AI models designed to handle complex reasoning and background tasks simultaneously while maintaining the natural feel of spoken conversation. The newly introduced models feature the ability to process real-time visual context without interrupting the user mid-sentence, alongside automatic detection and switching across 97 languages during a conversation.
Image source: DeepMind
Various Evaluation Metrics and Performance
According to published materials, Gemini 3.8 Live Extended Thinking recorded high scores on Artificial Analysis's Speech to Speech Quality Index and demonstrated robust performance in agent task completion benchmarks as well as Big Bench Audio, an evaluation metric for audio comprehension. Furthermore, Gemini 3.8 Live also ranked near the top for user preference in the Speech Agent Arena.
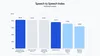
Image source: DeepMind
Application Features and Service Accessibility
Gemini 3.8 Live processes visual inputs in real time for use cases like onboarding guides or interactive tasks, while the Extended Thinking model provides natural conversational cues such as "Let me check that" and real-time progress narration when handling complex workflows. For general users, Gemini 3.8 Live is available in Search Live, while the Extended Thinking model can be accessed within Gemini Live and select subscription tiers of Google Workspace (Docs, Gmail, Keep).

Image source: DeepMind
Developer and Enterprise Environment Support
Developers and enterprises can utilize these models via the Gemini API and Google AI Studio, with support for building voice interfaces backed by real-time streaming infrastructure through developer platforms such as Agora, Fishjam, LiveKit, Pipecat, Vercel, and Vision Agents. Additionally, Google has applied its 'SynthID' watermark technology to its audio products to help identify AI-generated audio content.
Image source: DeepMind