AI Engineering Blogs
Curated deep insights from tech leaders and researchers — engineering, product, and strategy.
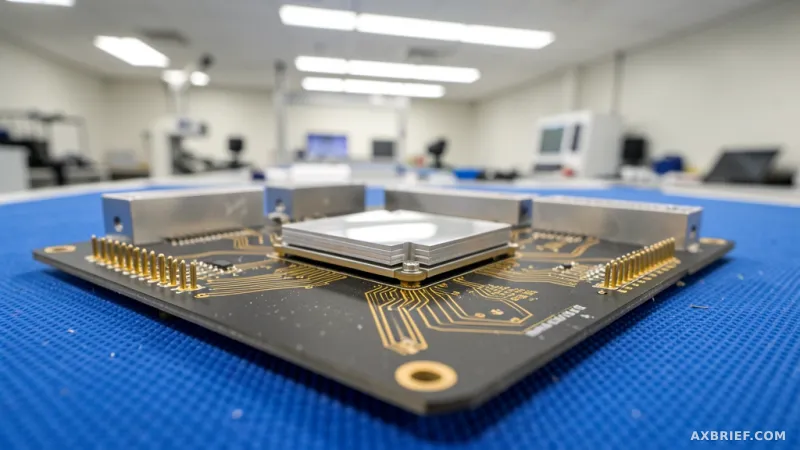
NVIDIA Groq 3 LPX Solves the Decode Latency Bottleneck for Agent AI
NVIDIA Groq 3 LPX achieves 3,400 tokens per second in long-context environments. The system splits workloads between Rubin GPUs and LPUs to
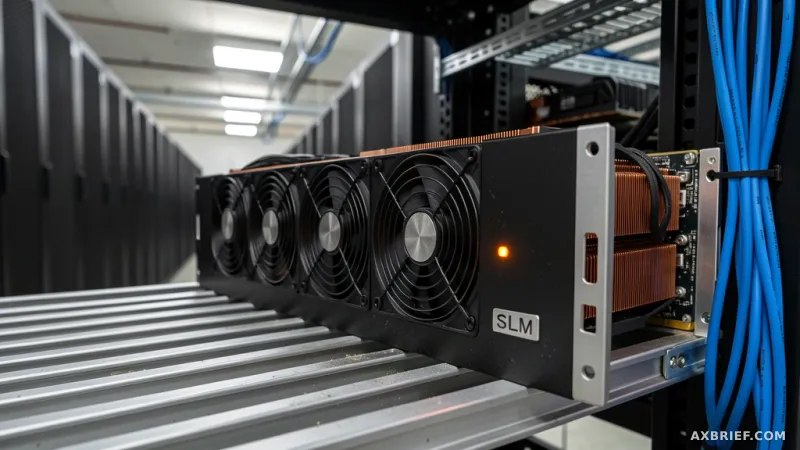
Why Local SLMs and Ollama are Replacing Cloud APIs for Devs
Local SLMs offer a secure alternative to cloud APIs by keeping data on-device. Ollama simplifies the deployment of quantized models across v
Grok Build Collapsed Data Analysis and API Deployment into 4 Prompts
xAI released Grok Build as a TUI-based coding agent powered by Grok 4.6. The tool automates the entire ML pipeline from data cleaning to clo
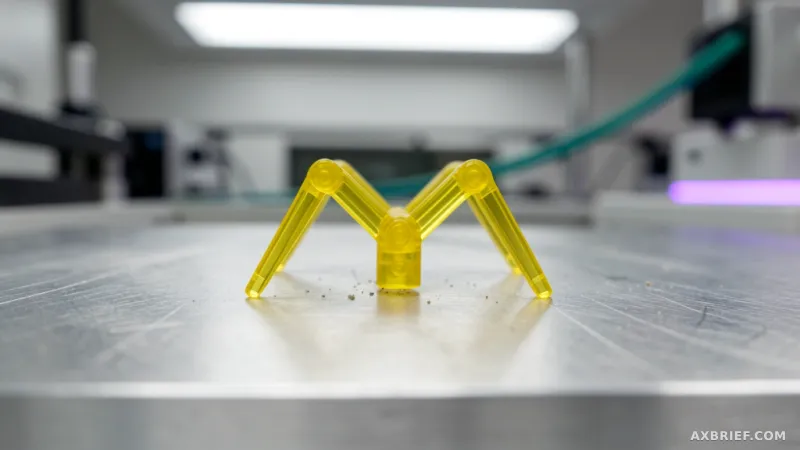
EPFL's 150-Microgram Robot Turns Sound Vibrations Into Thrust
EPFL developed a 150-microgram robot powered by sound vibrations. The device uses Helmholtz resonance to create active directional thrust. T
Foundation World Models: Trading Average Accuracy for Trust Guarantees
Florent Delgrange proposes a new framework for autonomous agent world models. The system prioritizes fitness for guarantee over simple predi
Amazon Bedrock RAG: Cutting Token Costs by 33% via Query-Aware Compression
Amazon Bedrock RAG costs drop by 33% using query-aware compression. Claude Haiku filters noise to reduce input tokens by up to 10.1 times. H
AI Agents Shift From Answering to Executing Across 5 Key Industries
AI agents are transitioning from text generation to autonomous execution. Five industries are seeing response times drop from days to minute
Muse Glimmer Hits 127 Tokens Per Second for Local Autonomous Coding
Muse Glimmer enables autonomous coding on local hardware. Speculative decoding pushes inference speeds to 127 tokens per second. The model e
Panasonic Avionics Slashes Diagnostic Time Using AWS Multi-Agent AI
Panasonic Avionics reduced IFEC diagnostic time from hours to minutes. The system integrates AWS Bedrock, LangGraph, and pgvector for automa
AWS ADOP Cuts Data Onboarding From Weeks to Hours
AWS ADOP reduces data onboarding time from weeks to hours. The platform generates deterministic PySpark and SQL code via Bedrock. Build-time
GPT-5.6 on Amazon Bedrock: Scaling Throughput via Cross-Region Inference
Amazon Bedrock introduces GPT-5.6 with a 1 million token context window. Cross-Region Inference allows scaling throughput via logical profil
ASR Benchmaxxing: When Low WER Means Your Model Isn't Actually Listening
Open-source ASR models are memorizing benchmark answers instead of recognizing speech. Low WER scores often correlate with a higher rate of
Google DeepMind's SIMA Controls Games Without Using a Single API
Google DeepMind introduced SIMA as a general-purpose game agent. The model operates using only screen pixels and natural language. SIMA enab
Amazon Bedrock Shifts FHIR API Security from Static Rules to Behavior
Amazon Bedrock enables behavioral baselines for FHIR API security monitoring. An asynchronous architecture ensures security analysis does no
Amazon Bedrock AgentCore Cuts IaC Time from Weeks to Minutes
Amazon Bedrock AgentCore reduced IaC development time from weeks to minutes. A multi-agent framework automated the migration of over 300 app
AWS S3 Vectors and OpenSearch: Solving the Vector Migration Tax
AWS integrates vector capabilities into existing stores to eliminate data migration. Amazon OpenSearch Service provides high-throughput hybr
The No-Code ML Pipeline Connecting Snowflake Data to QuickSight
Amazon SageMaker Canvas enables no-code ML workflows for Snowflake users. The pipeline automates model deployment from Snowflake to QuickSig
Amazon SageMaker and the Architecture of Vendor-Neutral AI Agents
Enterprise AI environments face fragmentation due to multi-model strategies. Separating the control plane from the execution plane prevents
Bedrock AgentCore Turns Natural Language Policies into Dogwood Code
Amazon Bedrock AgentCore now automates the conversion of natural language policies into Dogwood code. The system enforces stateful governanc
Why OpenAI Strategic Futures is Redesigning the Balance of Power
OpenAI launched the Strategic Futures team to study AI power concentration. The team analyzes how autonomous systems replace human-based gov
LFM2.5-DSpark Hits 140tok/s Inference on M4 Max MacBook Pro
LFM2.5-DSpark achieves 140 tokens per second on M4 Max MacBooks. A 300M draft model enables speculative decoding for faster inference. MoE a
Stampli Cuts Deep Finance Launch to 6 Weeks Using OpenAI Tools
Stampli reduced the Deep Finance launch cycle to six weeks using OpenAI. The company cut active production hours from 243 down to 77 hours.
GeForce NOW Brings 1440p Gaming to Firefox via play.geforcenow.com
GeForce NOW now officially supports Firefox for browser-based gaming. Ultimate members can stream games at 1440p and 120fps without local in
Virgin Atlantic Deploys Fetcherr AI to Solve Real-Time Pricing Complexity
Virgin Atlantic partnered with Fetcherr to automate airline ticket pricing. The new AI Market Model replaces static rules with real-time sim
Why KnowledgeForge Swapped Vector DBs for S3 Vectors and Claude 4.5
KnowledgeForge automates the conversion of ITSM tickets into knowledge bases. The system utilizes Claude 4.5 and S3 Vectors for serverless R
Google Gemini Targets Students With Free AI Plus and Deep Research
Google offers eligible university students one year of AI Plus for free. The new Student Hub integrates study notebooks and 3D visualization
How AWS Serverless IDP and Quick Automate Slashed Loan Processing to 6 Minutes
AWS GAIIC IDP Accelerator and Quick Automate reduce manual data entry. Loan processing time dropped from 20 minutes to under 6 minutes per f
Fanatics Handles 40 Requests Every 2 Minutes With Multi-Agent AI
Fanatics implemented a multi-agent AI system using Amazon Bedrock. The architecture handles 40 requests every two minutes during peak events
Bedrock AgentCore v1.2.0 Now Controls Web Search Domains and Dates
Amazon Bedrock AgentCore v1.2.0 introduces runtime web search filters. The update enables strict domain and date control for AI agents. New
Private Safety Processing: OpenAI's Answer to the ZDR Blind Spot
OpenAI introduced Private Safety Processing to detect complex attack patterns. The system identifies safety risks without accessing raw cust